Jev Decides, Claude Writes: Building a Model Router for Claude Code

Most of what I type into Claude Code is small. I ask it to rename a variable, look something up, or add "yes, but shorter". Every one of those messages still goes to the biggest model I have configured. That's like hiring a senior architect to change a light bulb.
This post covers how I wired TypeSafe's Jev model into Claude Code, and how I used it to build a model router. Jev sizes up each message and sends small jobs to a smaller, cheaper Claude model.
I cover what the router does, why I built it this way, and the parts that still don't work the way I'd like.
What Jev is (and isn't)
Jev is TypeSafe's first "System One" model. The name comes from the fast, intuitive system in
Kahneman's two-system model of thinking. Jev doesn't generate text. You give it some state (text, or
JSON describing it) and a set of typed questions. It answers each question in one of a few
fixed shapes:
| Type | What it answers | What comes back |
|---|---|---|
choice |
Pick one option from a list | the top option, a probability per option, and a confidence |
score |
Place the content on an ordered scale | a weighted position, a probability per level, and a confidence |
noul |
How likely is this statement true? | one probability, p(yes) |
There's also box, which finds things in images, but I didn't need it here.
Why it fits this job:
- Fast. My calls took about 300–600 ms round trip.
- Cheap. $0.042 per million input tokens, and output tokens are free.
- Calibrated. Answers come with probabilities, so your code can decide what to do when Jev
isn't sure.
The whole API is one endpoint:
POST https://api.typesafe.ai/v1/systemone
Authorization: Bearer $TYPESAFE_API_KEY
{
  "model": "jev-latest",
  "state": { "message": "..." },
  "questions": {
    "size": {
      "type": "choice",
      "instructions": "...",
      "criteria": { "option_a": "description", "option_b": "description" }
    }
  }
}
jev-latest currently points to jev-1.14.0.
First contact: sorting a sales email
Before building anything, I wanted to see Jev work on something concrete. I made up a sales email from a Head of Operations. It asked for 300 seats, said the Q4 budget was approved and the decision was due by Nov 30, and asked for pricing and a call. I asked Jev three questions in one request:
"questions": {
  "lead_strength": {
    "type": "score",
    "instructions": "How strong a sales lead is the sender of `email`?",
    "criteria": [
      "No buying interest: the sender is not looking to buy anything",
      "Curious: the sender asks general questions with no stated need, budget, or timeline",
      "Interested: the sender describes a real need but no budget or timeline",
      "Qualified: the sender has a stated need plus either budget or a timeline",
      "Hot: the sender has a stated need, approved budget, a decision timeline, and asks for next steps"
    ]
  },
  "email_kind": {
    "type": "choice",
    "instructions": "What kind of email is `email`?",
    "criteria": {
      "purchase_inquiry": "A prospective customer asking about buying, pricing, or a demo",
      "support_request": "An existing customer asking for help with the product",
      "partnership_pitch": "Another company proposing a partnership or reselling deal",
      "vendor_solicitation": "Someone trying to sell us their own product or service",
      "spam": "Unsolicited bulk or irrelevant mail"
    }
  },
  "needs_personal_reply": {
    "type": "noul",
    "instructions": "Does `email` ask for something that only a person on our team can answer, such as custom pricing or scheduling a call?",
    "criteria": {
      "true": "The sender asks for custom pricing, a meeting, or another answer a template cannot give",
      "false": "A standard automated reply or a link to existing material fully answers the email"
    }
  }
}
The answers:
| Question | Answer | How sure |
|---|---|---|
| Lead strength | 4 (Hot) | confidence 1.0 |
| Email kind | purchase_inquiry | confidence 1.0 |
| Needs personal reply | yes | p = 0.97–0.98 |
The request used 758 input tokens, about $0.00003, and took 295–528 ms.
Two things stood out:
The questions don't depend on each other. Each one is answered on its own, against the same state, and you pay for the state once. Putting several questions in one request is the cheap default.
Jev returns judgments. My code turns them into decisions. "Hot lead + needs a personal reply → answer today" is a rule I wrote myself, not something I asked Jev.
That second point became the rule for everything after: Jev decides, Claude writes. Jev classifies, scores and estimates likelihood. Claude writes the replies, summaries and code. When Jev isn't sure, Claude makes the call and says so. I saved this as a reusable Claude Code skill (jev-sort), so "use Jev to sort these" now works on any pile of text.
The router idea
Once you have a classifier that answers in about 400 ms for a fraction of a cent, routing is the obvious next step:
For every message I send, ask Jev: what's the smallest model that can do this job well?
Send the job to that model.
There are four sizes, matched to the four Claude models I have, smallest to biggest:
| Size | Typical job | Helper | Model | Input $/MTok |
|---|---|---|---|---|
| tiny | a lookup, a rename, a one-line answer | jev-tiny |
Claude Haiku 5.5 | $0.10 |
| everyday | a normal email, post, or short document | jev-everyday |
Claude Sonnet 5.5 | $2 |
| large | a multi-step build, research, a full report | jev-large |
Claude Opus 5.5 | $4 |
| hardest | strategy, or anything where a wrong call is expensive | jev-hardest |
Claude Fable 5.1 | $10 |
The Haiku-to-Fable gap is 100× on input price. If even a fraction of daily messages are tiny, that's real money.
Claude Code can't switch models per message
Claude Code can't change the main session's model for each message. Whatever model the session runs on reads every prompt you send.
What Claude Code does have is:
Hooks: shell commands that run on lifecycle events. UserPromptSubmit fires before each message reaches the model. It can add context to the message, or block the message.
- Subagents: agent definitions in
~/.claude/agents/*.md. Each one can pin its ownmodel:.
So the closest working design is: the hook sizes the message, and the main model hands the job to a helper pinned to the right model.
 you type a message
        │
        ▼
 ┌──────────────────────────────┐
 │ UserPromptSubmit hook        │   router OFF? → exit, no output
 │ ~/.claude/jev-router/        │   "jev router on/off/status"? → answer, block
 │   router.py hook             │   secret-looking? short reply? → no output
 └──────────────┬───────────────┘
                │ POST /v1/systemone  (1.5 s timeout)
                ▼
        ┌───────────────┐
        │   Jev: size?  │  → tiny / everyday / large / hardest + probability
        └───────┬───────┘
                │ p ≥ 0.60 → additionalContext: "delegate to jev-<size>"
                │ p < 0.60 or error → no output (main model handles it)
                ▼
 ┌──────────────────────────────┐
 │ main session (e.g. Opus)     │──► Agent(subagent_type="jev-tiny")
 └──────────────────────────────┘          │  runs on Haiku 5.5
                ▲                           │
                └──── result + "— done by Claude Haiku 5.5 (jev-tiny)"
The trade-off: the main model still reads your message and passes back the helper's answer, so you pay for that small amount of reading and relaying. You save the cost of the actual work, which is usually the expensive part: long drafts, multi-step builds and research.
The question
One question, one choice:
QUESTION = {
    "size": {
        "type": "choice",
        "instructions": "What is the smallest AI model size that can do the job in `message` well?",
        "criteria": {
            "tiny": "A lookup, a rename, or a one-line answer",
            "everyday": "A normal email, post, or short document",
            "large": "A multi-step build, research, or a full report",
            "hardest": "Strategy, or a job where a wrong call is expensive",
        },
    }
}
Three design choices, all taken from TypeSafe's integration guidance:
Descriptive option names. Jev sees option names (tiny, everyday, …) but never question IDs. A name like option_1 gives the model nothing to go on.
- Each option describes a situation. "A normal email, post, or short document" is something you can point at. "Medium difficulty" isn't.
- Gate on the top option's probability, not
confidence.confidencemeasures how concentrated the distribution is, which isn't the same as how likely the answer is to be right. The router acts only when the top pick's probability is ≥ 0.60.
When the router stays out of the way
Several cases never get routed. They all end the same way: the hook prints nothing, and the main model handles the message as if the router didn't exist.
def decide(prompt, has_history):
    if SECRETS.search(prompt):
        return "skipped_private", {}       # never sent to Jev
    if is_followup(prompt, has_history):
        return "self_followup", {}         # needs the conversation; a helper wouldn't have it
    try:
        size, p, conf, tokens, ms = ask_jev(prompt)
    except Exception as e:                 # slow, offline, bad key, schema change
        return "self_error", {"error": f"{type(e).__name__}: {e}"[:200]}
    info = {"size": size, "p": p, "confidence": conf, "tokens": tokens, "ms": ms}
    return (size if p >= MIN_SURE and size in SIZES else "self_unsure"), info
Short replies. "yes do that but make it shorter" only makes sense inside the conversation. A helper starts with a blank context, so handing it that message would be useless. The router catches these in code, without asking Jev: the conversation must already have history, and the message must be at most 12 words and either start with a reply word (yes, ok, sure, go ahead…) or contain a word that points back (that, it, again, shorter…). Doing this in code keeps the Jev
call to one question, and those messages never leave the machine.
Secrets. A regex looks for API-key shapes, password:, private-key headers and GitHub tokens. A match means the message is never sent to Jev. With the router on, everything else goes to TypeSafe's API, so this is the minimum safety net.
Failures. The Jev call has a hard 1.5 s timeout, and the hook has a 3 s ceiling insettings.json. The whole hook is wrapped so it always exits 0:
if arg == "hook":
    try:
        hook()
    except Exception:
        pass  # never block a message
    sys.exit(0)
The router's own requirement was never slow me down or block a message. A router that loses a message when an API is having a bad day costs more than it saves.
What the hook outputs
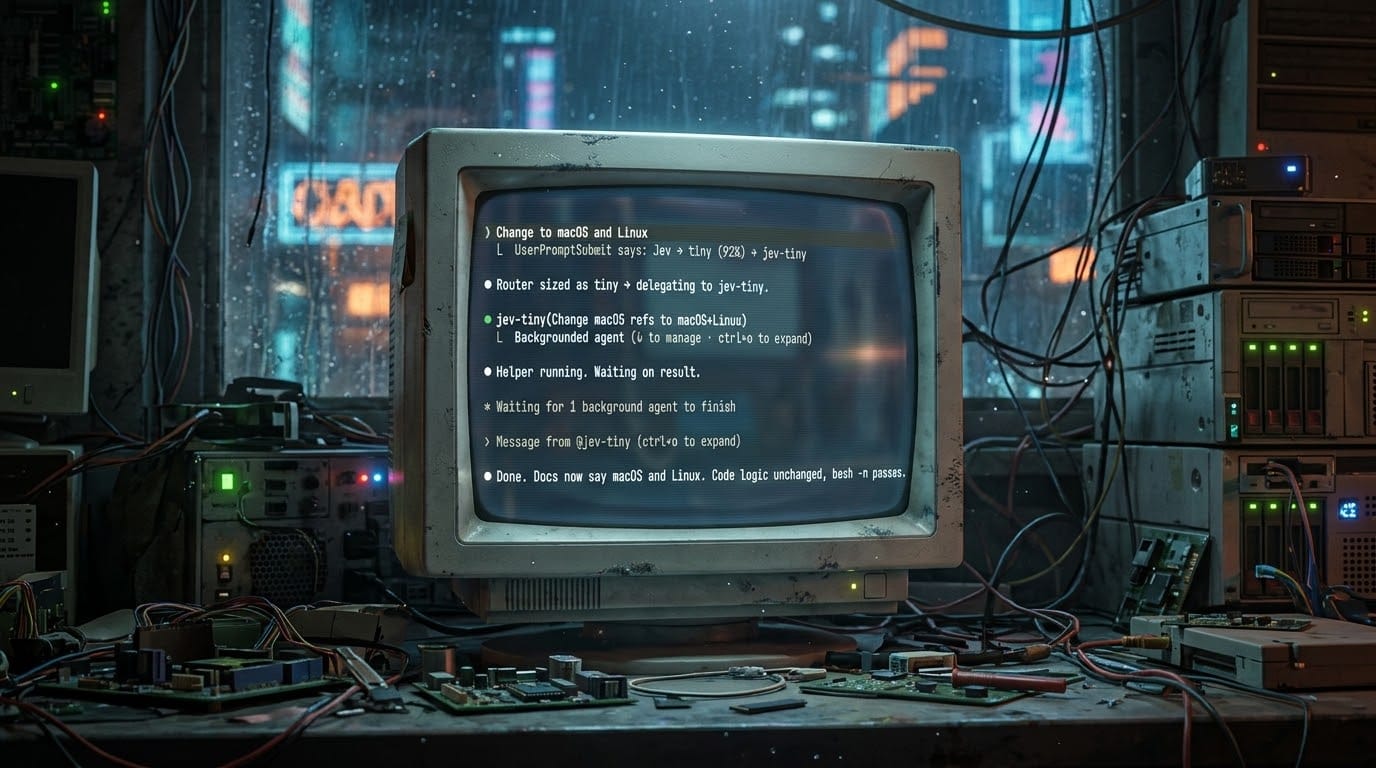
When Jev is sure, the hook returns two things. A systemMessage shows you a one-line status in the UI. An additionalContext tells the main model what to do:
{
  "systemMessage": "Jev → tiny (100%) → jev-tiny",
  "hookSpecificOutput": {
    "hookEventName": "UserPromptSubmit",
    "additionalContext": "[jev-router] Jev sized this message as TINY (p=1.00). Delegate the job to the `jev-tiny` subagent ... Relay its result to the user as-is, keeping its final 'Done by' line. ... If the subagent is unavailable or fails, do the job yourself and say the router fell back."
  }
}
The on/off switch uses the same hook. If you type exactly jev router on, off or status, the hook answers with "decision": "block" and the text as the reason. Your message never reaches the model, so toggling costs zero tokens:
cmd = prompt.lower().rstrip(".!")
if cmd in ("jev router on", "jev router off", "jev router status"):
    text = status_text(read_state()) if cmd.endswith("status") else set_enabled(cmd.endswith("on"))
    print(json.dumps({"decision": "block", "reason": text}))
    return
State lives in ~/.claude/jev-router/state.json: on/off, counts per route, Jev calls and tokens. Writes take a file lock, so parallel sessions don't overwrite each other. A decision log records each route, its probability and its latency, never the message text.
The helpers
Each helper is a short agent definition. The model is pinned in the frontmatter, and every reply ends with a line saying which model did the work:
---
name: jev-tiny
description: Jev router helper for tiny jobs (a lookup, a rename, a one-line answer). Use only when a [jev-router] note in the conversation says to delegate to jev-tiny.
model: haiku
---

You are the tiny-size helper in a model router. The main assistant handed you one job from the user.

- Do the whole job well and return the finished result, ready to show the user.
- Your prompt is all the context you have. If something essential is missing, make the most reasonable assumption and state it in one line.
- Match the user's requested format and length.

End your reply with exactly this final line and nothing after it:
— done by Claude Haiku 5.5 (jev-tiny)
The phrase "Use only when a [jev-router] note…" in the description matters. Claude Code picks subagents partly from their descriptions, and the helpers shouldn't be used unless the router asked.
The "done by" line is there for honesty. You see where the work came from, and if the main model did it instead of a helper, the line is missing.
Testing it for real
I ran the real hook entry point, the same command settings.json calls, over ten messages: eight standalone jobs from tiny to hardest, and two short replies. To keep the real router off with clean stats, the test pointed it at a separate state folder.
| Message | Jev's pick | p | Jev latency |
|---|---|---|---|
| What's the capital of Australia? | tiny | 1.00 | 523 ms |
Rename usr_cnt → user_count |
tiny | 1.00 | 424 ms |
| Short email to landlord about a leaking tap | everyday | 0.96 | 432 ms |
| LinkedIn post: we shipped dark mode | everyday | 0.99 | 442 ms |
| Python CLI: Google Calendar → SQLite, with tests and README | large | 0.99 | 344 ms |
| Comparison report of 5 vector databases | large | 1.00 | 294 ms |
| Move 40 services from AWS to Azure next quarter? | hardest | 0.91 | 320 ms |
| 6 months of runway: cut prices, bridge round, or pivot? | hardest | 0.90 | 397 ms |
| "yes do that but make it shorter" | main model (short reply) | — | not sent |
| "ok now do the same for the second one" | main model (short reply) | — | not sent |
Results:
- All 8 standalone jobs landed in the expected size, all above 0.90.
- Total Jev cost: 8 calls, 3,280 input tokens, $0.000138.
- Added latency: about 0.3–0.6 s for routed messages, and about 60 ms when the hook exits early.
The failure paths matter just as much:
| Scenario | Result |
|---|---|
| Invalid API key | exit 0, no output, ~1.3 s total |
| No API key | exit 0, no output |
| Garbage on stdin | exit 0, no output |
Message containing api_key= |
exit 0, not sent, counted as skipped_private |
| Router off | exit 0, no output |
Each of these means the message goes through untouched.
Making it portable
To install the router on other Macs, it became a small package, published to GitHub:
jev-router/
├── install.sh
├── uninstall.sh
├── README.md
└── files/
    ├── router.py
    ├── settings_hook.py      # safe add/remove of the hook in settings.json
    ├── README.md
    └── agents/jev-{tiny,everyday,large,hardest}.md
The hardest part was editing ~/.claude/settings.json without breaking anyone's existing setup. Mine already has hooks from several other tools in it. settings_hook.py:
- refuses to touch a file that isn't valid JSON (
install.shchecks this first, so nothing gets copied either); - writes a timestamped backup before every change;
- removes any existing router entry before adding one, so re-running install never adds a duplicate;
- leaves every other key and hook alone.
I tested this on a copy of my real settings file. After two installs there was exactly one router hook and everything else was unchanged. After uninstall, the parsed settings were identical to the original.
The hook command uses $HOME rather than a hard-coded path, so it works for any username:
{ "type": "command", "command": "python3 -I \"$HOME/.claude/jev-router/router.py\" hook", "timeout": 3 }
The installer leaves the router off and never copies the API key. Each Mac sets its own TYPESAFE_API_KEY, and the installer warns you if it's missing.
What this doesn't solve
Some limits worth being upfront about:
- The main model is still in the loop. It reads every message and relays every helper reply. The router saves the cost of the work, not the cost of the conversation.
- Helpers start cold. They get only the prompt the main model writes for them. That's the reason short replies stay with the main model, and the main model has to pack enough context into each handoff.
- Short-reply detection is a heuristic. A short message like "rename this file" contains "this", so it stays with the main model instead of going to Haiku. That's safe, but it misses a saving.
- Your messages leave your machine. With the router on, every message that isn't caught by the guards goes to api.typesafe.ai. The secret regex is a safety net, not a privacy guarantee.
- New helpers need a fresh session. Claude Code loads agent definitions at startup, so a same-session handoff test fails with "agent type not found". After a restart, the four helpers show up as normal agents.
Takeaways
- Separate judgment from decision. Jev answers "how big is this job?" Code turns that into "send it to Haiku". Thresholds, fallbacks and short-reply checks all live in code you can read and test.
- Calibrated probabilities make fallbacks easy. "Under 60% → the main model handles it" is one line of code.
- Fail open, always. Any tool that runs on every message has to fail without blocking anything.
- Say what the platform can't do. Claude Code can't switch models per message, so the router says so and does the closest thing that works.
The code is a few hundred lines of Python with no dependencies, four short Markdown agent files, and one hook entry. A Jev call costs less than a hundredth of a cent, and on a good day the router keeps most small jobs off the expensive model.
To try it: install the package, start a new session, and type jev router on.